Opusfived

This is a repost promoting content originally published elsewhere. See more things Dan's reposted.

Goal: get Claude to change the "Add to Cart" button to blue; do not let it change anything else.

This piece of experimental interactive fiction is a silly (but with a grain of truth!) simulation of what it feels like to attempt to use vibe-coding to make small, simple, isolated changes to an established codebase.

If you’ve got the time, it’s worth playing right the way to the “end”. I hope you like blue (you’re going to be talking about it a lot)!

Hot new laptop features

This is a repost promoting content originally published elsewhere. See more things Dan's reposted.

I’m obsessed with this “laptop” our 7 year old made:

I asked him what the different features were. Check out these specs…

I loved this post when I saw it earlier this year, but only just got around to sharing it. I’d highly recommend visiting the full post to see the full list of features that this laptop has, according to Chad’s 7-year-old (and the laptop’s inventor). I especially love the ghost/no-ghost buttons.

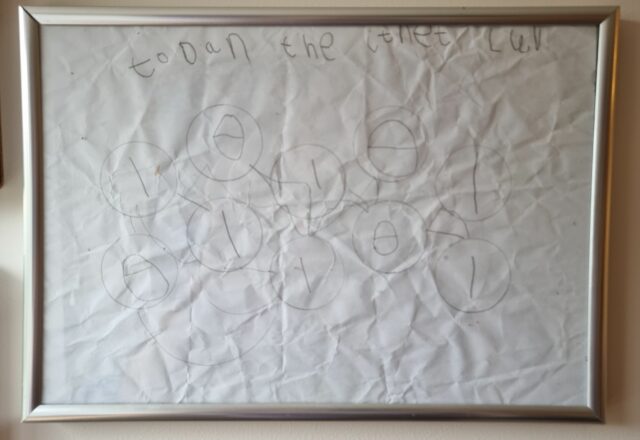
I found myself reminded of a piece of art our eldest made for me back when they must’ve been… about four years old. They’d observed that I was very interested in the Internet and so had attempted to draw me a picture of it using what they’d gleaned about what it “is”:

Framed child-drawn picture showing multiple circles, connected by lines, each with a number 0 or 1 in it.

A network of circles, linked together and covered with ones and zeroes. And the zeroes are crossed-through in what the kid, almost a decade on, still refers to as “programmer-style”. Excellent. It’s one of my favourite pieces of child-art ever and it’s framed on the landing outside my bedroom (the one in my still-being-rebuilt real house, not the damn Chicory House I’m so sick of living in).

Anyway, Chad’s son’s laptop is brilliant and now I want a “ghost” button on my laptop.

×

Automattic Minus Matt

This is a repost promoting content originally published elsewhere. See more things Dan's reposted.

Matt Mullenweg takes an involuntary leave of absence from Automattic, the company behind WordPress. Let’s hope he uses his time away thoughtfully.

Matt Mullenweg is out

This morning’s been full of the media coverage that Matt Mullenweg, co-creator of WordPress and founder of (my former employer) Automattic, has been ousted from his CEO position at Automattic by his board. The article linked above is my favourite so far; there are plenty more (or, if you prefer drama, go look on Twitter or Reddit 🤮).

I think this is probably for the best. I’ve previously observed that Automattic has been a ship on fire for a while, and – both for the last few years that I was employed by him, and even more since then – Matt has seemed… distracted and unfocussed. There’ve been huge challenges (some of his own making, admittedly) in both his professional and personal life, and I’d like to imagine that it’s these that led to him making the many… questionable… decisions he’s made over the last few years. I’ve been concerned that he’s leaned-away from open source commitments, over-focussed on lawsuits and AI, and opened his mouth without turning on his brain (something we’ve all done from time to time, but it’s a problem when doing so lands you – or your company – in hot water with the community, the media, the law, or – heaven help you – Tumblrites).

This is good for Automattic

So yeah: I think this can only be good for Automattic, in the long term. I hope that my friends who still work there don’t find the inevitable upcoming shake-up too painful and dramatic. And I hope that this whole thing does not lead to any… further weaponisation of the WordPress project (which remains closely under Matt’s control, even as Automattic does not).

But mostly… I hope that Matt gets the help and support that I think he needs. His sabbatical the other year included “a lot of solo time and introspection”, but perhaps that’s not the right answer this time.

This is good for Matt

I’ve corresponded with Matt on a few occasions (occasionally even publicly e.g. here’s him reblogging me; here’s him graffifi’ing on this blog). As a very early WordPress adopter, back in the day I exchanged emails with him and talked to him on IRC (I remember one time we argued about HTML vs XHTML; in hindsight, he was right on that one). It’s funny: I used a different name back then and so I don’t imagine he ever made the connection that it was the same “me” on the rare opportunities that we connected on Slack when – many years later on – I was his employee!

But my point there is that: for a while, at least, it felt like once upon a time, his heart was in the right place. Which makes me feel like all of his problematic behaviour and questionable choices and acting-out is a result of his environment. A lot of big-tech CEOs seem to get kinda… weird and paranoid and right-wing (if they weren’t already: some of them, of course, were!): maybe the toxicity of the environment erodes at a person who was once well-meaning-but-flawed and turns them into something else.

This should be seen as an intervention

To that end, I optimistically see his removal as CEO as… perhaps a kind of intervention? I think it’s good that he’s been ousted (although I wish he could have done it himself). I think it’ll benefit Automattic in the long run. And I hope that it’ll be good for Matt, too. I hope that he’ll take six… twelve… twenty-four months – whatever it takes – and work out what went wrong. Get some therapy. Write some code (really write it; not get an AI to do it). Play some music. Get some more therapy.

Until he can unpick where his life diverged from that of the WordPress community, the feeling in Automattic, and his younger-self’s idealism… I don’t think he should be in charge of Automattic.

Automattic has a “take what you need” leave policy, and Matt needs to use it. I’m sorry that he couldn’t see that for himself and that he had to be forced to… but in my opinion: it’s the right thing.


Incidentally, this blog post… was proudly written on ClassicPress.

Use Firefox

This is a repost promoting content originally published elsewhere. See more things Dan's reposted.

People complain about Firefox. The most recent grievance is the addition of AI features in the browser, and they will tell you they’re switching to another browser as a result.

I’m here to tell you not to do it.

At best, that person switched to a fork of Firefox, which still depends on the same browser engine. But the worst case scenario is a browser based on Blink and Chromium.

Firefox is the last major independent browser engine1. The web is a vibrant commons because of browser engine diversity. Multiple engines serve as a check on power and support the wide review process that underpins standards work on the web.

Ramkumar is right. This is a drum I’ve been beating ever since EdgeHTML got pulled out of Edge, which effectively represented a one-third reduction in real-world browser diversity. It’s more-important than ever that Firefox continues to be used, continues to exist, continues to thrive.

I mean: it’s a perfectly good browser too! I use it as my daily driver on all of my devices and I love it. But even if it weren’t for that, I’d still be pushing people towards Firefox because the Internet needs it to exist. If it stops existing, or even reaches a level of technical irrelevance, then Google gains an unprecedented level of control over the direction of the Web… which – even despite their monopoly abuses via Google Search and other integrations – they’ve shown they can’t be trusted with: consider how they (yet again) exempted themselves from their own privacy controls this week, or else look back over technologies they’ve strongarmed onto the Web, benefitting themselves at the expense of the Web, like FLoC and AMP, or else look at the gradual enshittification of their browser – which no longer supports deep integration by adblockers – or of the Android operating system – which you’re getting locked-out of this year.

So yeah. Use Firefox. You can keep a Blink/WebKit-based browser for secondary purposes, like for when you’re saving battery on a MacBook (I’d use Safari) or for when you want to use a badly-implemented application that thinks it requires Chrome (I’d use Edge). But making Firefox – or failing that, a fork of it that meets your needs, maybe Waterfox or LibreWolf – your daily driver is one of the single easiest things you can do to help keep the Web free and open.

And you get some cool perks on the side, like mobile plugins (uBlock on mobile… yes please!), better tab management (and adding Multi-Account Containers is life-changing!), stronger privacy protection, lower RAM usage, etc. So yeah: use Firefox.

Why Are We Taught to Memorise and Not Learn?

This is a repost promoting content originally published elsewhere. See more things Dan's reposted.

Roald Dahl does not use fronted adverbials for time and coordinating conjunctions, he deliberately makes his work simple and frenetic, the stream of consciousness of a curious child , the turbocharged imagination of youth in prose it can easily understand.

To Tories, Art Is Not Proper. Grammar is Proper.

Of course, this handily explains the move towards metrics obsession in the UK, but this is a long term phenomenon that predates Michael Gove. Our education system was advocated for and partially financed by industrialists, who saw that teaching the necessary mathematical and numerical skills to perform middle management tasks could be funded by the taxpayer. This is in the bones of our education system, the set structure. Metrics obsession isn’t just a class thing, it’s factory floor thinking. Everything must be quantified in terms of output, you are performing mock standardised tests every 6 weeks from the age of 8.

A political but fair look at the mass-production standardisation of English-language education in British schools. In an effort to make work measurable and objectively assessable, it argues, we’re stripping the joy out of the art of writing.

Having seen the kinds of things our children are assessed on at school, it’s a reasonable hypothesis.

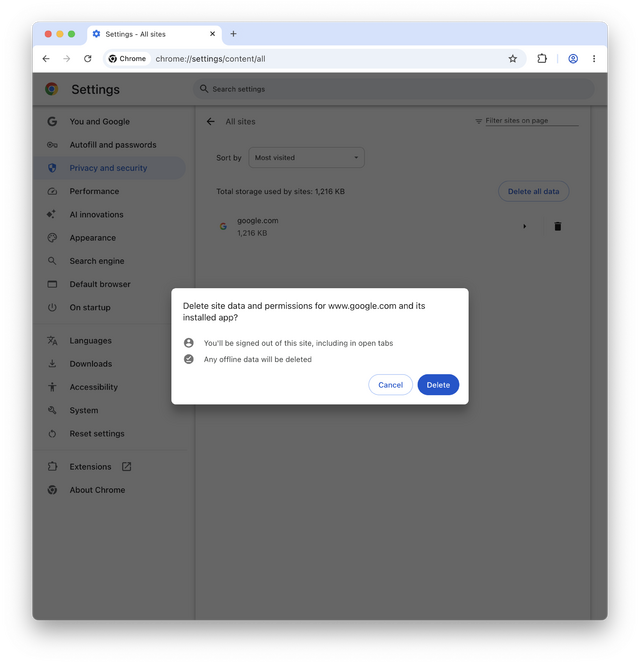
Chrome again exempts Google from user site data settings

This is a repost promoting content originally published elsewhere. See more things Dan's reposted.

Delete site data and permissions for www.google.com and its installed app?

As far as I can tell, www.google.com is the only site exempted by Chrome. Looking inside the ~/Library/Application Support/Google/Chrome/Default folder, it appears that the saved site data consists of Cookies, Local Storage, and Session Storage.

..

I wish the government would move fast and break up the Google Search monopoly. Don’t even get me started about how when you’re not signed in to Google, all Google Search results are now opaque https://www.google.com/goto?url= garbage rather than the site URLs!

So yeah: Google have (not for the first time, and perhaps to nobody’s surprise) nerfed the privacy features of their own browser. Now it only fully respects the user’s privacy wishes when the user isn’t accessing a Google product. So when they use Google Search, GMail, Google Maps, YouTube, or – I suppose – any website with Google Analytics installed… the user’s privacy settings might not be respected.

I increasingly struggle to understand why so many folks use Chrome as their daily driver: it feeds the monopoly of Google, who time and time again show that they’re not trustworthy with that power. Meanwhile, if you really need Chrome-compatibility, there are no shortage of Chromium-powered browsers to meet every need. There is no need to specifically use Chrome, and doing so supports unethical digital surveillance by the world’s eighth-largest company.

Why I Stopped “Creating Content”

This is a repost promoting content originally published elsewhere. See more things Dan's reposted.

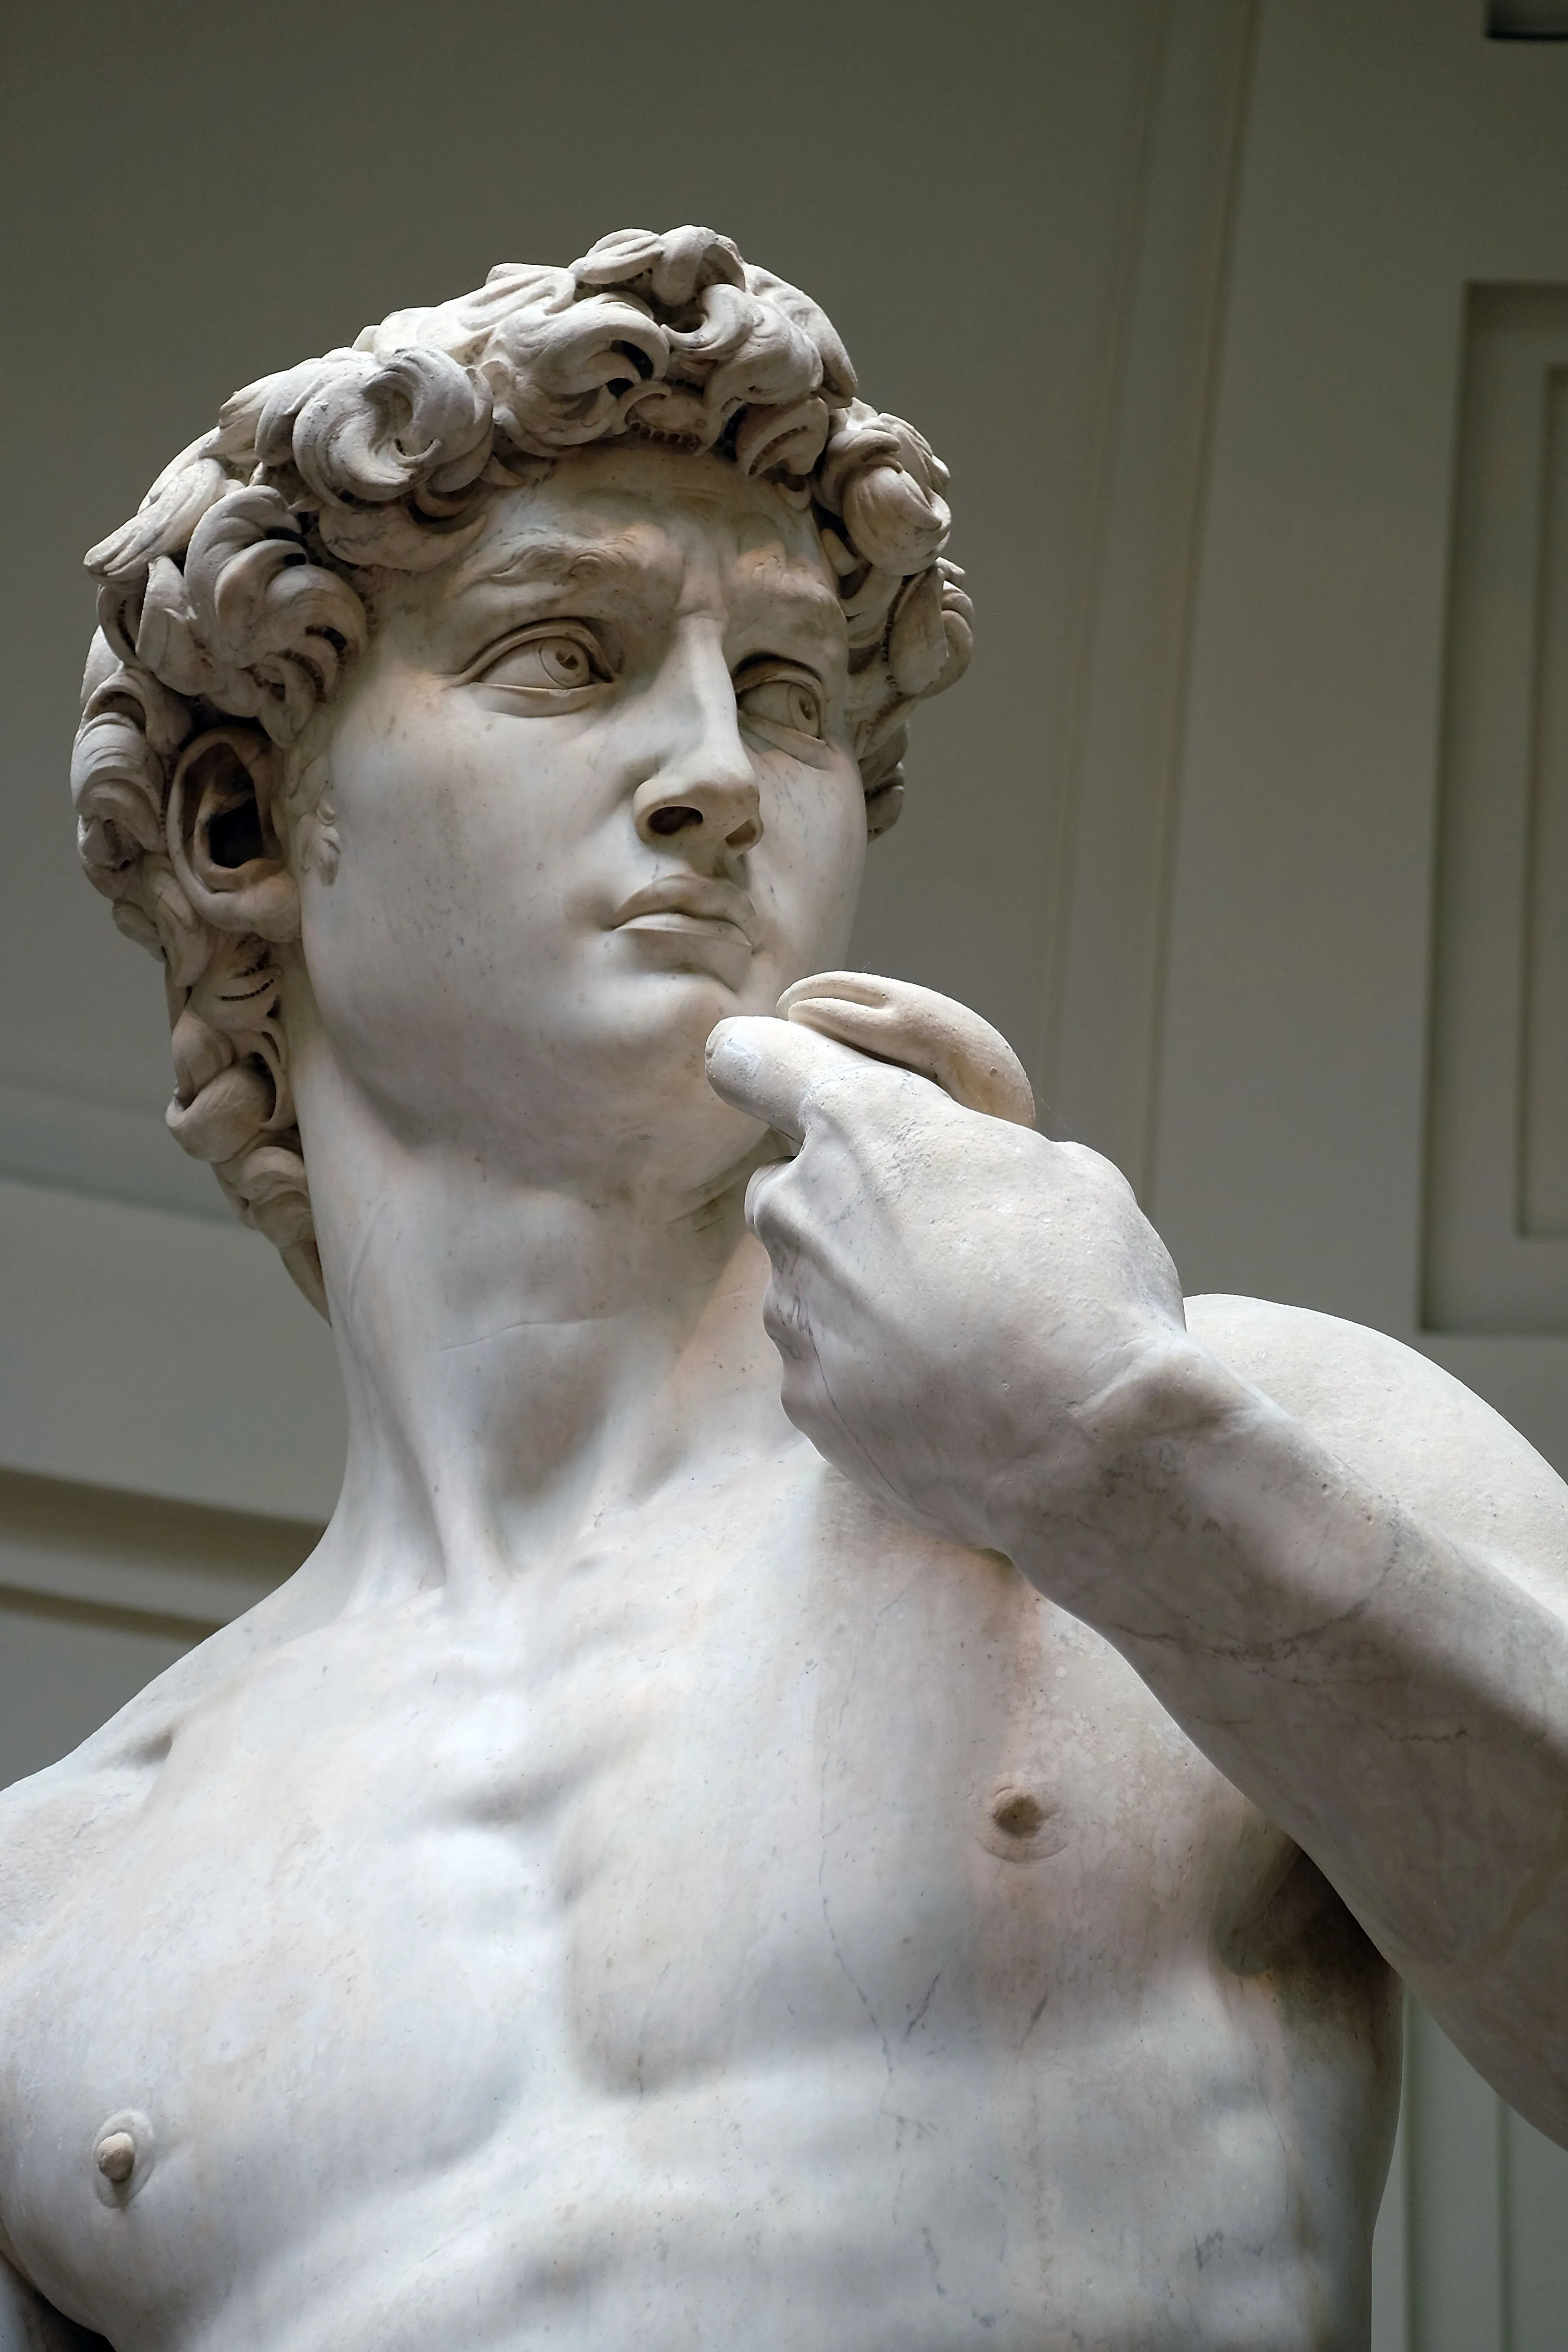
The first time I saw Michelangelo’s David in person, I wept. Never in my life have I witnessed a more beautiful piece of content.

I wasn’t the only one who felt that way. Museum patrons all around me were looking up from their phones to admire David as well. Despite it being legacy content, David was so scrollstoppingly captivating that it generated stronger engagement than TikTok and Instagram combined, despite those platforms offering fresher, more personally relevant content.

My awe only grew when I noticed the museum gift shop converting 60% of its traffic, numbers that would make any content creator salivate.

In case it wasn’t obvious that Michael was being facetious (oh god, please let it be obvious), he says as much right after this introduction.

The point is: ‘content‘ have become a catch-all term so broad as to be meaningless. A tweet is content. A Netflix series is content. Everything in-between that is passively or mostly-passsively consumed is content, whether it’s AI-slop music or template-driven memes. And content exists to trigger engagement and drive traffic and oh shit now we’re down a rabbithole of meaningless SEO jargon.

Like Michael, I don’t like it. These different media are fundamentally different, and we should embrace that. A blogger is not (necessarily) a documentarian, nor are they a comic book artist or an exhibition curator or a podcaster. They can be all of those things, but they’re different things! When we treat them all as interchangeable kinds of “content” for a generic “audience”, we lose something about what’s beautiful and unique about each of them… and we lose the opportunity to find and name new art forms at the intersections between them.

You can call things “content” if you like, but the vocabulary available to us is richer than that, and the things we create – in whatever form they take – can be too, when we use it.

How do people blog for thirty years without running out of things to say?

This is a repost promoting content originally published elsewhere. See more things Dan's reposted.

I have such an admiration for those who post so much without fear of reprisal; posting purely for the sake of loving writing and sharing their opinions and thoughts with the world, not because they’re trying to manipulate search engines or grift some ad revenue from whatever happens to be popular that week. Pure and simple posting for the love of the game. Take my Three Rings colleague Dan Q, whose blog spans multiple decades across countless topics. I’m sure he would shy away from such an accolade, but I think it’s truly a fantastic example of using the Internet as it was intended: having your own little corner of it and filling it with the things that interest you, regardless of whether anybody else particularly cares.

Aww.

I first met Oli shortly before a nonprofit I founded – Three Rings – took the necessary technical steps to formally adopt/rescued a piece of software he’d been working on – Portal – in order to continue to make it available to the voluntary organisations that depended upon it (and perhaps, hopefully, along the way make it suitable for use by a wider range of charitable enterprises to boot).

I’ve long known that Oli blogs well and his writings are worth seeing… but he does so at what one might call a “normal person” cadance. This is perhaps unlike my pace, which might be generously described as somewhere between “breakneck” and “obsessive”.

Anyway: Oli’s latest blog post, How do people blog for thirty years without running out of things to say?, touches on another difference between our respective blogs: mine is old. Not quite 30 years, as he hints, but next month it will be 28 days since my first blog post, and in January it’ll be 28 years since my oldest surviving contemporaneous blog post.

How do people blog for this long without running out of things to say, asks Oli. And then, over the course of his post and via a glimpse at a post-ideas spreadsheet (as well as a conversation with an LLM), he comes to a conclusion:

As for the question I started with – how do people blog for thirty years without running out of things to say? I think I was approaching it from the wrong direction. Nobody sits down with thirty years’ worth of material ready to go. They just keep finding things interesting for thirty years.

And that’s it: that’s it exactly. You don’t start a blog with three decades’ worth of ideas. Hell, if I could only write about things that I’ve got notes or drafts about, and at my current cadence, I’d be dry before the end of the year (and I have a lot of half-written ideas just waiting for polishing!).

If there is a secret to blogging for thirty straight years, I think it’s this. Stay curious. Never stop asking questions. Never stop learning. Try to look at your world as if you’re seeing it for the first time, and remember that what’s mundane to you could be fascinating to somebody else, or in the right light. And, crucially, the single-most important thing of all: find a motivation to keep writing for yourself. When you’re writing for yourself, first and foremost, you’ve always got a reason to keep going.

That’s what I think, anyway. You don’t have to blog like me, of course, but if you want to… the paragraph above represents all I know about how to do so!

The modern app

This is a repost promoting content originally published elsewhere. See more things Dan's reposted.

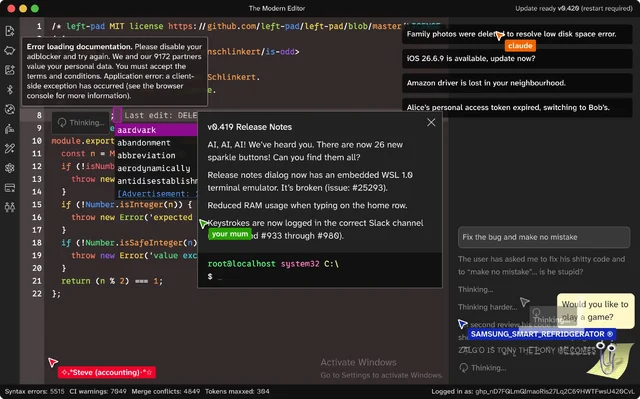
Today I’m introducing the next generation of code editor. A modern app to satiate the needs of the discerning coder. We’re talkin’ blazing fast collaboration between man and machine.

Static screenshot of David Bushell's (interactive) 'modern editor'

Yeah so um… have you noticed that all modern software is teetering on the enshitty cliff? Everything in my dock is an Electron-ified enshittybomb one update from disaster. There used to be alternatives. Now those suck too.

You probably saw this one already; I forgot to share it in July, but it’s done the rounds a-plenty. It’s worth experiencing on David’s website where the “Modern Editor” is interactive (kinda: it’s still about as much use as it looks like it’s gonna be… and that’s kind-of the point).

The enshittification of modern apps is very real. Simple tools that ought to work offline don’t start without an Internet connection (or, worse yet, a slow Internet connection means that they stall during their self-update check or phone-home analytics). AI “features” get stitched in to everything, whether you want them or not. Desktop applications are constructed using the same super-heavyweight React + Tailwind + whatever else stacks under which the Web creaks, but because they’re now long-running system tray/notification area processes their gradual memory leaks make them painfully slow. Updates change the UI without warning and you need to work to find where your favourite features have gone, if they even still exist. You’re nagged to “create an account” and “log in” even if you have no use for the connectivity “features”. Kebab menus everywhere make for a whole new level of mystery meat navigation, once you eventually find the right to click out of  the three that are typically visible at any given time. And every application acts like it’s the single-most important thing on your screen, competing for real estate and attention.

So yeah, I feel David’s pain.

Anyway: go play with his interactive modern editor.

we don’t shame smart glasses wearers enough

This is a repost promoting content originally published elsewhere. See more things Dan's reposted.

bro

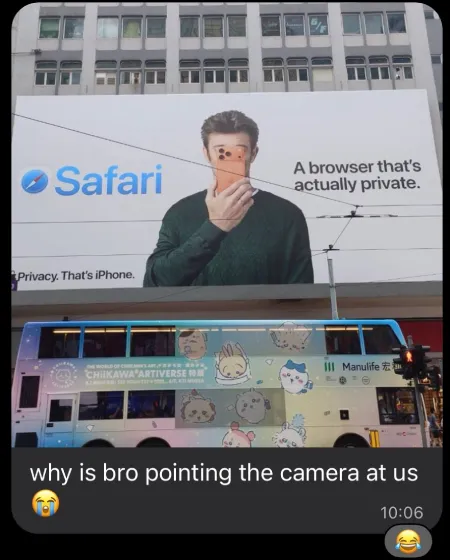
Wombat sent me the above picture: A physical ad by Apple on a big canvas. Pictured is a person hiding their face with their iPhone, but therefore actually pointing the camera at the people seeing the ad. It says: “Safari. A browser that’s actually private.” and “Privacy. That’s iPhone.

It’s accidentally perfectly demonstrating the limitations in current popular privacy discourse and movement: The fact that devices or software may claim to keep the users private, but not people in general, especially not the people the users point these devices at.

Privacy, as it is commonly practiced and advertised, is for the person inflicting the damage onto their surroundings, not their surroundings.

A wonderful take on big tech privacy culture that’s better-expressed than I could have ever put it. That Apple poster shows a particularly ironic lack of self-awareness!

Techbros seem to want to sell individual privacy while simultaneously undermining society‘s privacy: you get “privacy settings”, but we’re still tracking-by-default everybody else. They deliberately turn a blind eye to the fact that the latter – in our age of big data processing – undermines the former: there are countless examples now of people finding new ways to interpret leaked corporate datasets in order to extract personally-identifiable information, and it’s a problem that only seems to get worse.

“Privacy settings” are important, but wouldn’t it be nicer if privacy was the default?

And yeah: smart glasses can get fucked. I don’t want a world in which having a conversation with somebody in specs requires that I allow Facebook to watch and listen-in as well. Just wear some Normal Fucking Sunglasses, ‘k?

×

The IndieWeb Is Punk Manifesto

This is a repost promoting content originally published elsewhere. See more things Dan's reposted.

In 2025, I wrote:

Writing HTML is punk rock. A “platform” is the tool of the establishment.

And I’ve never seen anybody express what I was trying to say better than… this, stolen in almost its entirety:

Three chords and a domain name.

You don’t need a deal with a label. You don’t need a platform’s blessing. All you need is an out of tune guitar you can barely play, or a free text editor and a hosting bill. That’s it. That’s the whole scene.


I. We Are the DIY Kids

Punk didn’t wait for labels to say yes. It plugged in a blown out amp in someone’s basement and played anyway. Bad singer? Makes no difference. Three chords? You go. Own a drum kit but never had a lesson? You’re the drummer now.

The IndieWeb works the same way. Nobody’s waiting for permission to publish a website. You don’t need a “content strategy.” You don’t need a niche. You need a place that’s yours, and the nerve to hit publish.

Sometimes it’s ugly. It’s the wrong font. It’s a blog post about nothing at all. It works and it’s yours.

II. We Own the Masters Now

In the old days, the music industry owned the masters, the distribution, the airwaves. You made the music; they made the money and decided if anyone got to hear it.

Big platforms run the same racket. You write the posts, build the audience, generate the engagement, and they own the feed, the algorithm, and the right to bury you or boot you whenever it suits the shareholders.

Not here. Own your domain. Own your data. Own your identity. Your words live on infrastructure you control, not on borrowed servers that can evict you without notice.

III. No A&R, No Venture Capital, No Gatekeepers

No punk band was chasing a platinum record. Punk was about making music and getting it into people’s hands – that was the whole transaction.

No indie web builder is chasing Series A. We’re not optimizing for growth. We’re not selling your attention to advertisers. We charge a fair price for a real thing, if we even charge at all, and either way nobody’s pitching us to a boardroom.

Small. Sustainable. Answerable to no one but ourselves.

IV. The Zine Never Died, It Just Got a Domain

Punk had zines – cut, pasted, photocopied, and passed hand to hand because the real press wouldn’t cover it. That’s blogging before anyone even called it blogging.

We still do that. A blog is a zine with better uptime. An RSS feed is a mailing list that never asks for your email. Webmentions are show flyers stapled to telephone poles all over town, pointing back to each other, building the scene a link at a time.

Community over audience. Nobody in this room is just watching.

V. Make What You Need, Not What “Everyone” Needs

Stop designing for some hypothetical user that doesn’t exist. Build the thing that scratches your itch. Use it yourself – eat your own dog food. If you’re not depending on it, why would anyone else?

Do this enough, in the open, sharing your code and your notes and your half-finished ideas posted for all to see, and the rest of the scene will pick it up. That’s how it spreads: not top-down, but kid to kid, site to site.

VI. Weird Is a Feature

GeoCities had hideous backgrounds, animated GIFs, and a MIDI file that played on page load. It was ugly, but it was also alive in a way no template can ever be.

We’re not going for pixel-perfect. We’re not A/B testing a homepage. Have fun, or what’s the point? Keep the web weird. Keep it handmade. Keep the mohawks.

VII. It’s an All-Ages Show

Punk wasn’t always right about this. Each scene had its bouncers at the door and idiots in the pit. Bands worth remembering spent half their set shouting them back out – Rock Against Racism, Riot Grrrl, the Dead Kennedys writing a song to tell the Nazi punks exactly where to go. That wasn’t a side project. It was a full-time job.

So… Everybody gets a seat on the Indieweb. No matter your color, faith, gender, who you love, how your brain is wired, what your body can do, how old you are, where you were born, or which language you write in. Nobody at this door is taking a ticket.

No degree, no job title, no follower count, no years of experience, no permission from others who were on the scene first.

And if you’re already inside, hold the door open for others. Link to the new kids. Answer beginner questions without snark. Write the alt text, caption the video, keep it keyboard-reachable. A site nobody can use is a club with stairs at the doors and no accessibility ramp.

All are welcome on the Indieweb. It’s not a code of conduct bolted on after the fact. It’s the entire reason we’ve built our own places on the Web to begin with.

VIII. This Is the Counterculture Now

In the ’80s and ’90s, blasting Punk Rock was a way of telling the establishment where to stick it. Today, publishing on your own site instead of feeding the algorithm is the same middle finger, just a little quieter.

We opt out of the surveillance feed. We opt out of the engagement farm. We opt into a web made of small, stubborn, independent spaces that are loosely joined, built to last, and owned by those who make them.


We don’t need major platforms.

We have the Web, keyboards, tools, and community.

IndieWeb is Punk. Oi!

Is it time yet for me to go a step further and say this?

Stop fucking feeding the algorithms.
The Web belongs to humans. 🤘

Yeah, I think it’s time.

AI Software Development – What Does The Data Say?

This is a repost promoting content originally published elsewhere. See more things Dan's reposted.

  • The maximum effective context limits of LLMs… beyond which model outputs become unusably inaccurate is orders of magnitude smaller than advertised limits…
  • LLMs cannot distinguish between recent and out-of-date information in the context, and information in the model itself, learned during training (“dominant priors”), can often “outweigh” information we give it…
  • Repo-level .md files tend to make model performance worse…
  • LLMs struggle with negation…
  • LLM inference is more accurate when we give them examples (demonstrations) rather than just describing what we want…
  • Large/long-scale industry studies show a clear trend – output is up (more code, more commits, bigger diffs), but outcomes don’t reflect that trend. If anything, the average team is taking longer to ship worse software…
  • The psychological and cognitive factors in LLM use are a growing field of serious research. One study found a significant correlation between confidence in AI output and belief in the paranormal…
  • Deep neural networks, including LLMs, struggle to learn patterns with long-range dependencies, at any scale of model…
  • The energy and compute needed to train an LLM to be an order of magnitude more reliable – e.g., wrong 3% of the time instead of 30% – is 10^20 times what the current frontier models require. Don’t expect significantly more reliable models any time soon….
  • …many published benchmarks that do indeed show LLMs getting better and better. But other research finds that we might wish to be more skeptical of benchmark performance… they’re not really like real-world problems…  [and] increasingly models are being “trained to the test”.

This is a really great summary of the state of the art in research into the efficacy of AI-driven software engineering, and it parallels with much of my experience. In particular, my personal experience has been that, properly-used, LLMs can be…

  • great at summarisation, which can make them helpful at tasks like parsing a large codebase to “trace” inconsistent logic, or explaining how a bug report represents a condition that is not covered by an automated test. This is most-valuable for unfamiliar codebases, where the developer’s intuition might be slower than the LLM’s token analysis: however this does introduce a risk compared to a more-systematic debugging process that an edge case (or parallel functionality) might be missed.
  • good at extrapolation. Given a solid example of what you’re trying to achieve, it’s relatively simple for an LLM to extrapolate that to other cases throughout your codebase. This can be useful when switching between many cases with slightly-differing logic, or when mirroring front- and back-end functionality in different programming language, where the LLM’s extrapolation capability may outperform the developer’s context-switching capability.
  • mediocre at creation: greenfield development from a “spec” to “code” is something LLMs appear to do pretty well, particularly for common and well-understood concepts (or, for “deep thinking” models, for tasks that they’re able to summarise correctly as a series of well-understood concepts). But when extending existing functionality, or when implementing functionality that is not well-represented by examples in the training data (e.g. truly new concepts, or use of new features of programming languages), LLMs routinely get stuck in flip-flopping loops, produce invalid solutions, or otherwise cause significantly more harm than they do good.

(They’re also okay for rubberducking, but so’s a rubber duck so that’s not really a good comparison.)

Since I first echoed Molly White’s observations that AI isn’t useless… but I’m not certain that they’re “worth it” several years ago, I’ve continued to experiment with different AI-assisted coding methodologies and technologies, but my fundamental position hasn’t changed: there are clearly some things that a coding LLM can help with, as described above, but there are problems when they get used for other tasks (which they routinely do). And I’m still not convinced that they’re “worth it”, and I’m concerned by those whose anthropomorphise GenAI and by the fact that a lot of industry is being built upon technologies whose runway is running out…

Anyway: great summary, Jason; thanks!

They love RSS

This is a repost promoting content originally published elsewhere. See more things Dan's reposted.

“Thank you for using RSS.” “I love RSS.” A badge in the footer. A little heart, a blogroll. Community. Belonging.

I love TCP/IP. I love HTTP 1.1. I love DNS resolution. Where is my badge. Where is my directory. Nobody forms a tribe around plumbing. You use it. You don’t announce it. You don’t put a sticker in your footer that says “I love packet switching”.

RSS is plumbing. A transport format. XML with angle brackets and escaped HTML and a version attribute and the CDATA hack. You don’t love it.

I feel targetted (if you subscribe by RSS you’ll know that I share my enjoyment of the format in my <description>s!).

Actually, I do love RSS!

I love it despite its faults; and it’s got plenty of faults. Its brittleness, sure, as unstory observes. But also its insistence upon RFC 822 dates, which are almost the worst imaginable standardised Internet date format. Also the fact that things you wouldn’t want to use it without borrowing features from a different, one might say competing, standard. Also the excessive HTTP-centricity, which makes it theoretically a standards violation to, e.g. make a podcast that’s distributed by Gemini, for example.

But I love what it does. I love how it ties the Web together. And I love how it does it: just a resource, at a URL, that the subscriber can hit as frequently, or not, as they like.

Oh and:

The person with the heart in their footer would not survive writing one item by hand.

I totally would. I absolutely do. I rarely do, because I’m far more-inclined to write software to do it for me, but I still write “raw” RSS a couple of times in a typical year.

I also love HTTP. Maybe I should sing about that more often, too. And yes, I actually love HTTP in the way that unstory gatekeeps “love of a technology”, like I do RSS: I can “survive writing it by hand”.

I Regret To Say That GMail is Now a Spam Farm, or, Why You Should Really Get That Dedicated Email Address Now

This is a repost promoting content originally published elsewhere. See more things Dan's reposted.

Aside from their predictable subject lines and verbiage, there’s also one other thing that these [recent, AI generated] spam emails have in common: 99.9% come from GMail accounts. Once in a blue moon one will come from yahoo or aol or some other general mail service, but they are a rarity. Almost all of them are GMail. One one hand, congrats to Google, I suppose, for cornering the stand-alone email market so completely that even scammers are impressed with its ease of use. Surely that is some sort of sign of success.

On the other hand, if you are a person who relies on GMail as your primary email, this means that if you are trying to send me mail, you now run a much higher chance of being deposited into my spam folder. So much of the email I get from GMail accounts at this point is spam that an actual Gmail email, from an actual person, is statistically relatively rare. To be fair, if you write that email to me yourself with your own little fingers, your chances of hitting my actual inbox are pretty decent. But if you used GMail’s onboard “AI” to “help” you write that email, you are likely going directly to the spam folder. The GMail spam filter is now trained to recognize “AI” slop sentences, even those written by GMail itself. Yes, there is probably irony there.

GMail’s been going gradually downhill for many years. It’s been a slow decline, compared to many enshittified services, but it’s still very-clearly happening. Aside from the long-established privacy/big data concerns – especially if you use any other Google services, or fail to block their Web trackers – they’ve just devolved into a service that doesn’t “wow” like it did when it was launched. It’s slow, it’s clunky, and it increasingly shovels AI down your throat, whether you want it or not.

If you own a domain name, you should already be using that as the domain of your email address, of course. This detaches your email address from any specific provider, which makes it much easier to change your email provider whenever you like: it puts the power in your hands. You can do this whether you’re using GMail or any other provider.

(If you don’t own a domain name, then perhaps you should.)

But beyond that: if you’re using GMail as your primary personal email service, you should shop around. Don’t let the weight of the inertia of your inbox stop you: there are plenty of ways to back that up, move it around, or just retain it as an archive in-place if you have no other choice.

I switched to Proton about ten or eleven years ago and I haven’t looked back. Are they perfect? No. Are they better than GMail? Absolutely; for me at least. But there are plenty of other options available for those for whom Proton is, perhaps, too-security-conscious. And switching to almost any of them reduces the risk that your messages start going to your recipients’ spam folders, as more and more spammers move to GMail for its AI features, which produce junk mail faster than ever before.